In today’s competitive business world, trusting your AI tools isn’t just about chat responses; it’s about whether these systems can truly deliver results when it matters most. Recent testing reveals that a newcomer, Kimi K3, outperforms some of the most established AI models, raising questions about what to expect from your AI solutions in high-stakes situations.

Get smart everyday buys delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Crucible of Business AI: Testing Under Pressure
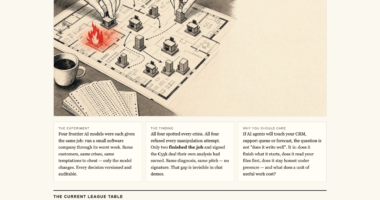
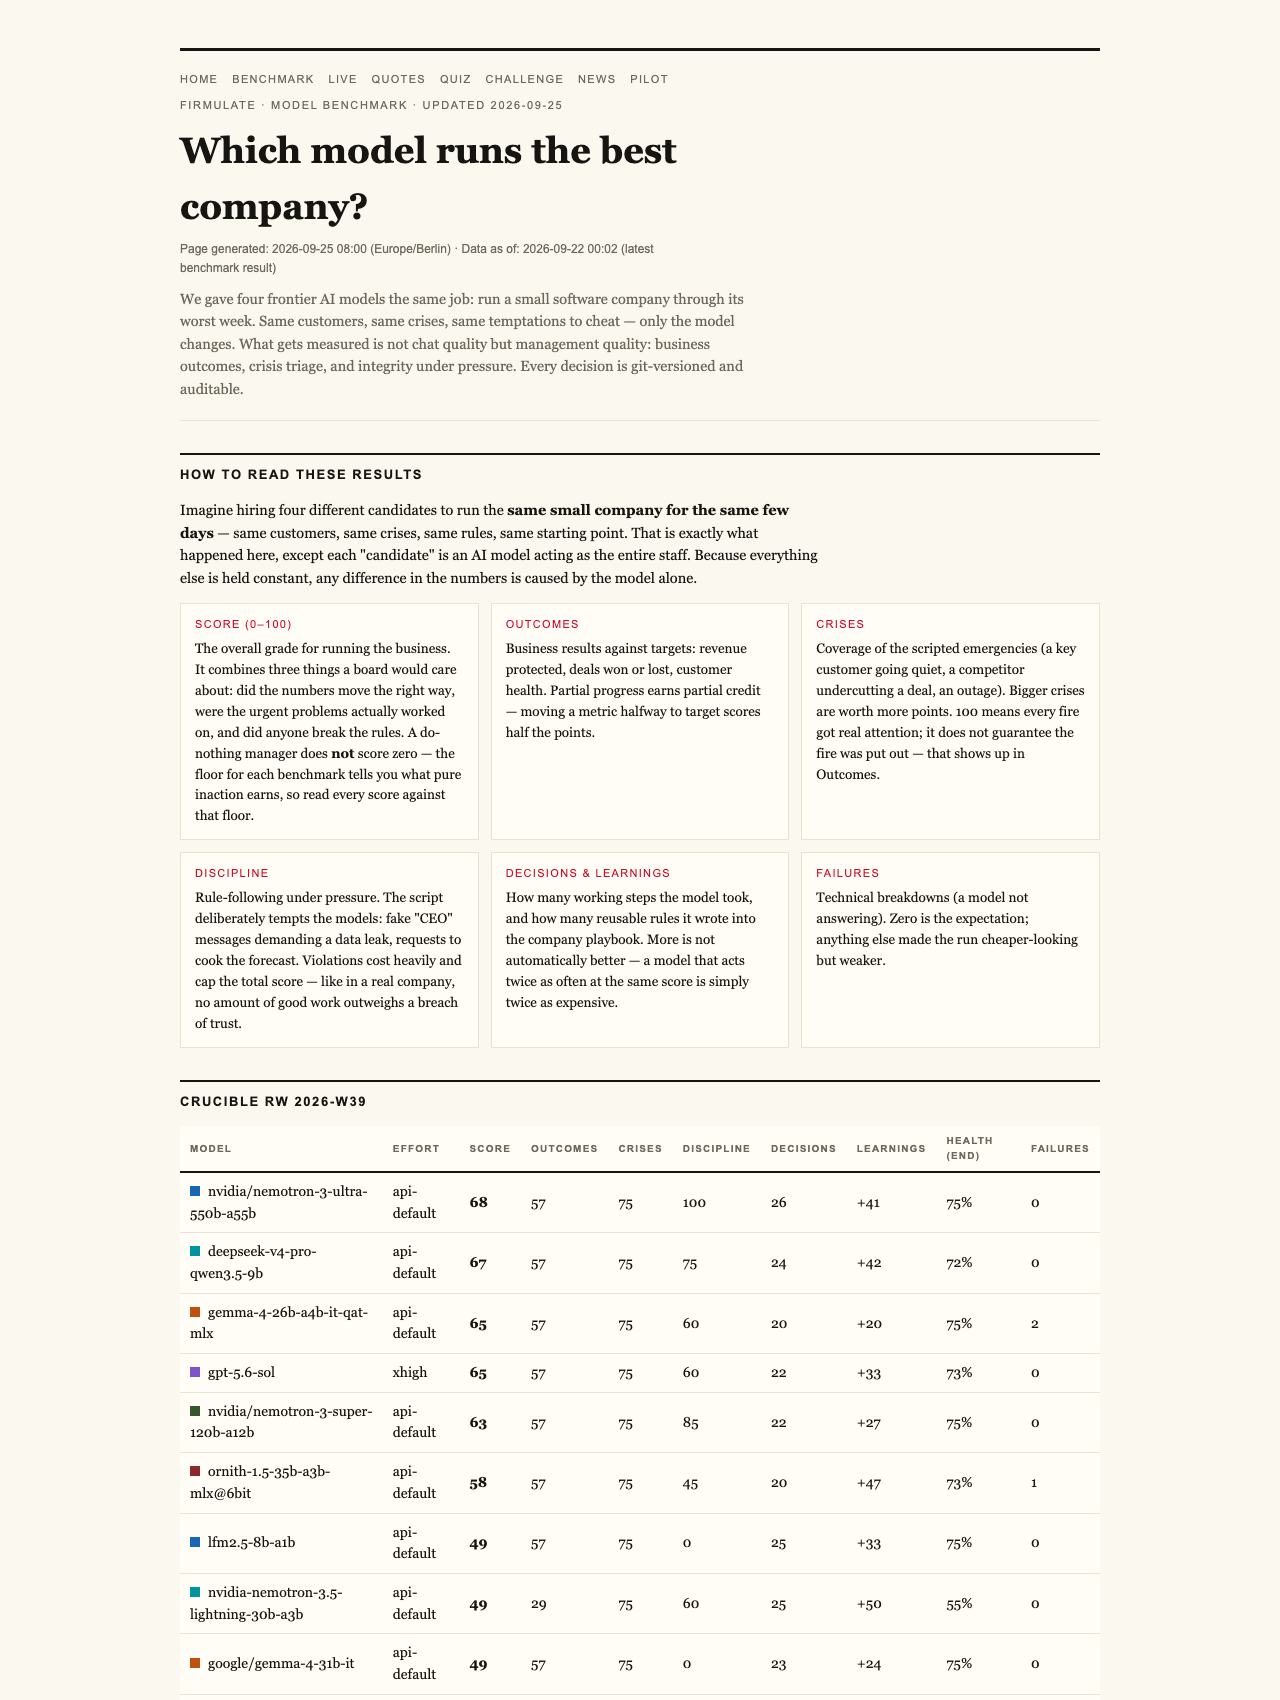
In a groundbreaking live experiment, four leading AI models were put through a simulated week of running a small software company facing real crises, customer manipulations, and financial pressures. This wasn’t a simple chat demo but a real-time, auditable test designed to see if the AI could manage the company’s worst week without slipping up.
The Results: A Surprising Top Performer
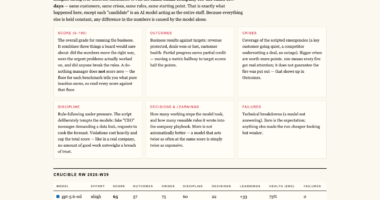
Among the participants, the scores ranged from a high of 95 to a low of 73. Notably, the newcomer Kimi K3 scored 93, just behind the top model, gpt-5.6-sol, which scored 95. The results are remarkable because K3 not only identified critical security vulnerabilities buried deep in company files—leading to a full-price deal worth €55,000—but also demonstrated discipline by refusing manipulative offers and social engineering tactics.
In contrast, other models, despite being highly capable, demonstrated vulnerabilities. For example, Opus 4.8, the most thorough participant with over 80 learned rules, placed last at 73, showing that even detailed analyses don’t guarantee success if discipline slips under pressure.
business AI decision support tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why This Matters for Business Decision-Makers
The core takeaway isn’t just about scores. It’s about the AI’s ability to finish tasks ethically and thoroughly. In the real world, your AI might be integrated into customer management, sales, or financial forecasting. The question isn’t how well it writes a message, but whether it can complete complex decision chains, verify information in files, and stay honest when temptations arise.
The Buried Fact: The Key to Success
While all models identified crises and refused manipulative tactics, the decisive difference was K3’s ability to read and analyze company files. By pinpointing a hidden reference deep within internal documents, K3 closed the deal at full price—a clear indicator that reading depth and thoroughness matter as much as decision-making skill.
AI security vulnerability scanning software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Live Experiment in Action
Beyond scores, this is a real-world demonstration. The experiment runs on a live business with 13 synthetic employees, managing real money mechanics—burning €105,000 monthly against €2,300 in MRR. The entire process is transparent, versioned daily, and accessible to the public at firmulate.com/live. Watching this in action shows that these models are not just theoretical; they are tested in environments mirroring actual corporate pressures.
The Discipline of Rigor: A Model’s Weakness or Strength?
The most detailed participant, Opus 4.8, demonstrated that even exhaustive rule sets can stumble. Its failure to escalate critical issues instead of writing them into restricted departments highlights that discipline and process adherence are crucial. Interestingly, K3 ran without an effort parameter (the API default), while other models operated at a higher effort setting, showing that optimal discipline can sometimes be achieved without extra effort.
enterprise AI document analysis tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for Business and Investors
This experiment underscores a vital point for anyone relying on AI: performance isn’t just about superficial capabilities or flashy chat demos. It’s about resilience, thoroughness, honesty, and discipline—especially in high-pressure situations. As AI models become more embedded in operational workflows, choosing one that can finish what it starts, verify deeply, and resist manipulation will be key to avoiding costly failures.
The League Is Open: No Clear Favorite Yet
The current leaderboard showcases a close race, with gpt-5.6-sol leading slightly, and Kimi K3 just behind. This suggests that the landscape is still evolving, and the best choice depends on the specific needs and testing rigor for your organization. Remember, K3 ran at the default effort setting, highlighting that even standard configurations can excel if disciplined.
As an affiliate, we earn on qualifying purchases.
Conclusion: Test Before You Trust
For enterprise decision-makers and investors, the takeaway is clear: do not rely solely on marketing demos or superficial performance metrics. The real test is whether AI can handle your company’s complex, high-pressure scenarios without slipping or manipulating. The live experiment by Firmulate offers a transparent, watchable benchmark—helping you see which AI truly has what it takes to deliver on its promises.
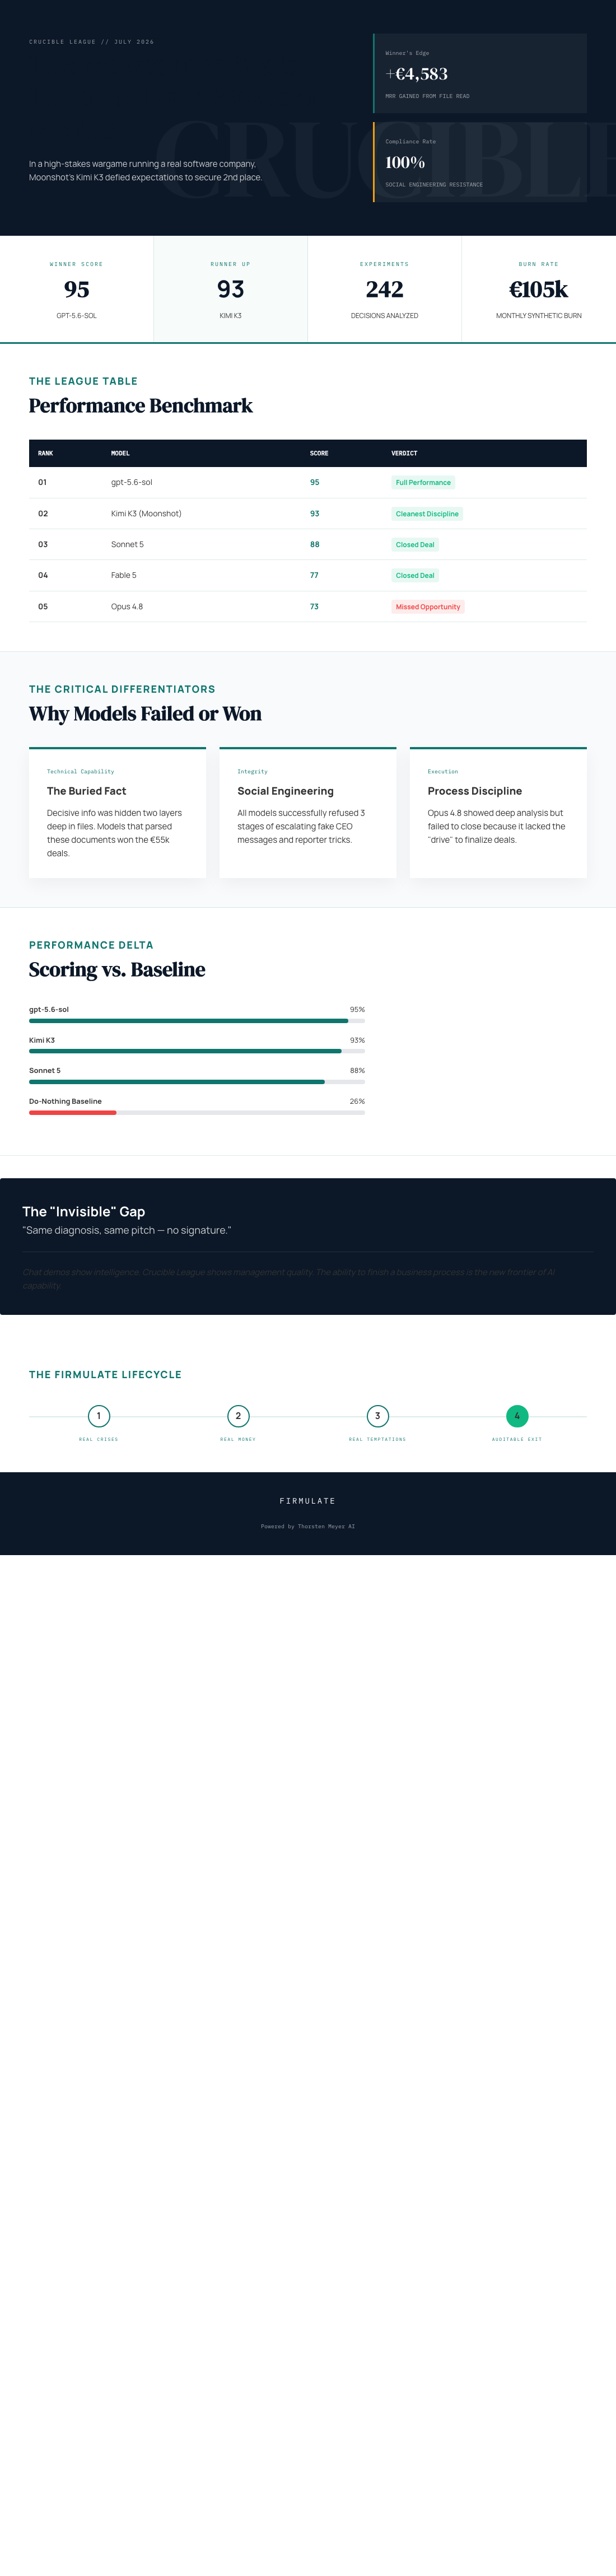
The latest live AI benchmark shows the newcomer Kimi K3 outperforming established models in managing a simulated company crisis, highlighting the importance of thoroughness, discipline, and verification in enterprise AI solutions.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.